How to Size PLC Systems for Reliable Control in Multi-Station Production Lines
Start With the Line’s Operating Model, Not the I/O List
When technical evaluators size PLC systems for a multi-station production line, the first question is often framed too narrowly: how many inputs and outputs are required? That number matters, but it is rarely the factor that determines whether a control architecture will remain stable, maintainable, and economically sensible after commissioning.
The more useful starting point is the operating model of the line. A multi-station line is not simply a collection of machines connected by conveyors. It is a coordinated system in which station availability, material flow, inspection decisions, safety zones, motion sequences, operator interventions, traceability transactions, and upstream/downstream dependencies all affect control performance.
In a simple standalone machine, a marginally undersized controller may result in a slightly slower response or reduced room for future modifications. In a linked production line, the same decision can create intermittent faults that are hard to diagnose: missed handshakes between stations, delayed reject actions, network timeouts during product changeovers, nuisance safety stops, or recovery sequences that require manual intervention. These failures are especially costly because they may not appear during factory acceptance testing. They tend to emerge only after the line reaches real production rates, product variation, and shift-level operating pressure.
For that reason, PLC selection should be treated as a control-capacity assessment rather than an I/O procurement exercise. The objective is to establish whether the chosen architecture can execute the required logic predictably, exchange data within the necessary time window, support safe recovery, and absorb foreseeable expansion without creating excessive upfront cost.
Define What “Reliable” Means for This Particular Line
Reliability is often discussed as a hardware property, but for PLC systems it is better understood as an outcome of architecture, application design, and operational fit. A high-end CPU will not compensate for unclear station ownership, poorly segmented networks, inconsistent device naming, or recovery logic that has never been tested under fault conditions.
Before comparing controller families, evaluators should document several characteristics of the production process:
- The target line cycle time, including whether the process is continuous, indexed, asynchronous, or batch-oriented.
- The number of stations and whether each station can run independently during downstream disruption.
- The speed and consequence of required inter-station handshakes.
- The quantity and type of field devices, including standard discrete I/O, analog signals, encoders, drives, vision systems, RFID, barcode readers, and weighing equipment.
- The role of safety functions, including whether safety is local to a station or spans multiple stations and transport zones.
- The required production records, recipe management, traceability, quality data, and connections to MES, SCADA, historian, or enterprise platforms.
- The expected change profile: new product variants, additional stations, packaging formats, inspection equipment, or regional compliance requirements.
These questions reveal why identical I/O counts can lead to very different PLC requirements. A 500-point assembly line using mostly pneumatic actuators and simple photoelectric sensors may be manageable with a modest controller and remote I/O. Another line with 500 points may include synchronized servo axes, multiple vision inspections, serialized product tracking, and a high number of drive diagnostics. The second line requires far more engineering attention even though the I/O count looks similar on a budget sheet.
Evaluators should also distinguish deterministic control from information exchange. A PLC may communicate successfully with a production database or an inspection server while still being unsuitable for time-critical control through that same path. Commands that affect guards, motion permissives, reject timing, or station release decisions need defined response behavior. Reporting data can normally tolerate more latency, retries, or buffering. Treating both traffic types as equivalent is a common source of unstable system behavior.
Cycle Time Is a Budget That Must Be Allocated
PLC scan time is important, but it should not be evaluated in isolation. The relevant question is whether the total control response time remains within the process window. That response includes field-device update time, network transport, PLC task execution, program logic, output update, drive or actuator response, and any filtering introduced to handle signal noise.
Consider a station that must detect a part, validate its orientation, coordinate a clamp, request a robot operation, receive a completion signal, and release the pallet. The line may tolerate a PLC program that executes in tens of milliseconds if the mechanical process itself takes several seconds. However, a high-speed reject mechanism, registration mark application, winding process, synchronized indexing system, or safety-related stop function may require a much shorter and more predictable response.
It is therefore useful to establish several timing classes rather than one headline scan-time target. For example, a project team may separate:
The point is not that every system needs highly specialized control hardware. It is that a line’s critical timing requirements should determine the architecture. Buying a larger CPU without separating task priorities can still leave a project exposed. Conversely, specifying an expensive motion-capable PLC for a line with mostly low-speed discrete control may add cost and programming complexity with little operational benefit.
A practical evaluation method is to ask the controls supplier for projected CPU utilization under normal production conditions, then review the assumptions behind that figure. Is the estimate based only on logic execution? Does it include communication load from drives, remote I/O, HMIs, safety devices, and supervisory systems? Is it based on the final program or on an early template? The precise acceptable utilization threshold depends on platform and application, but a design that operates close to its practical limit before commissioning provides little room for diagnostic logic, added devices, or production changes.
Centralized and Distributed Architectures Solve Different Problems
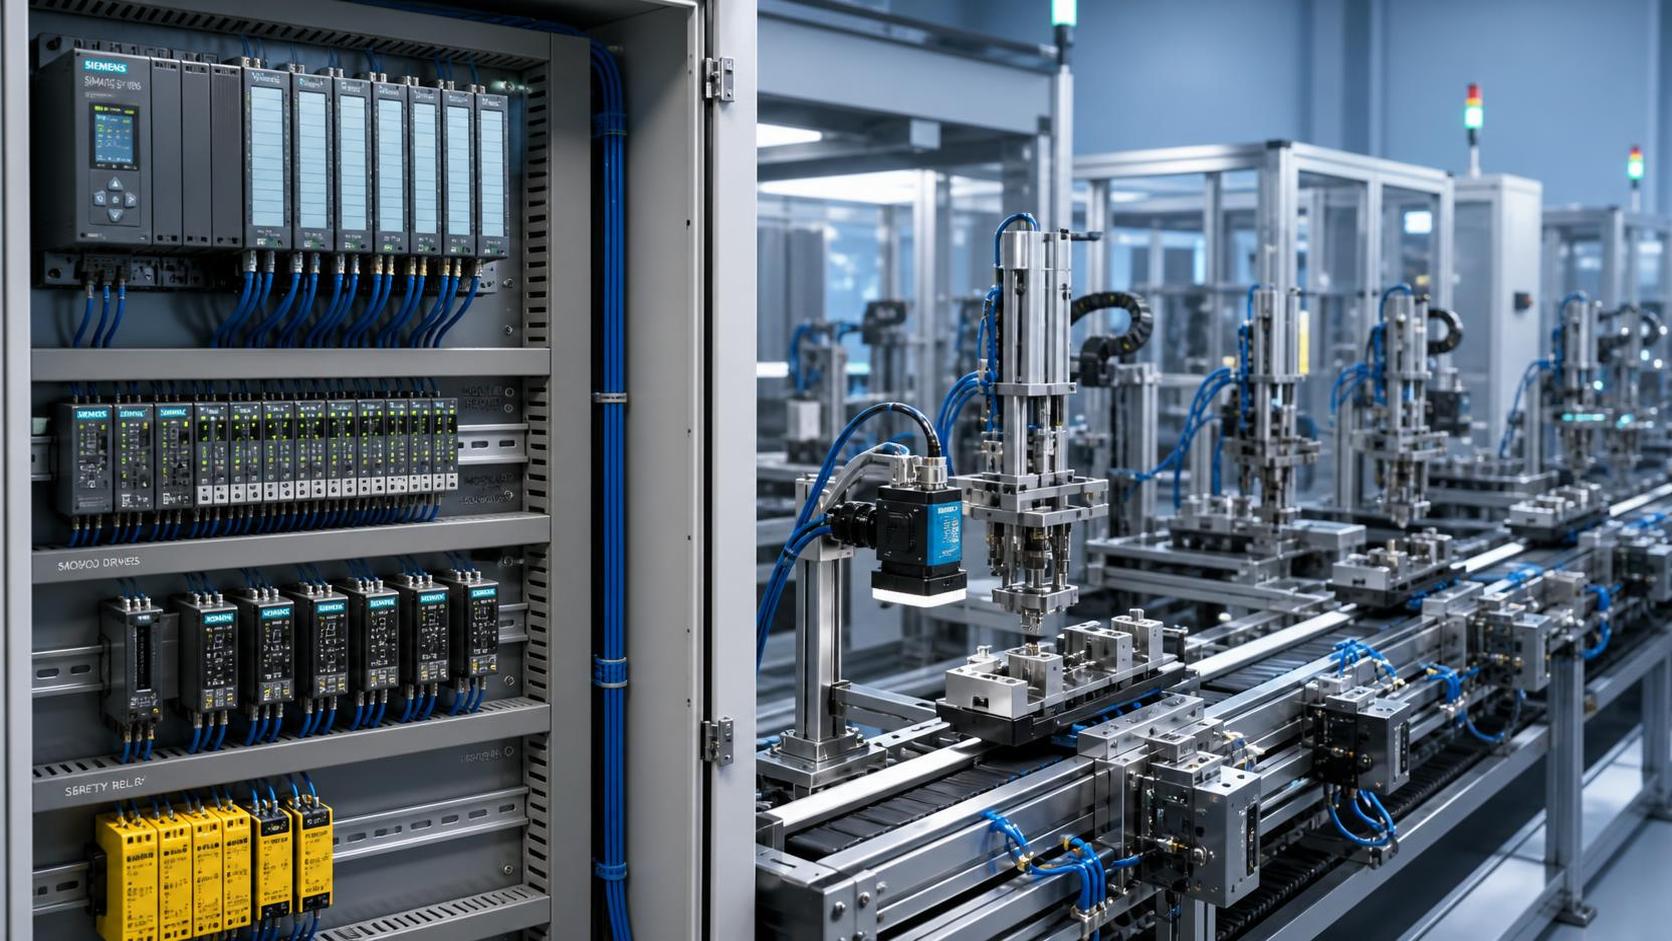
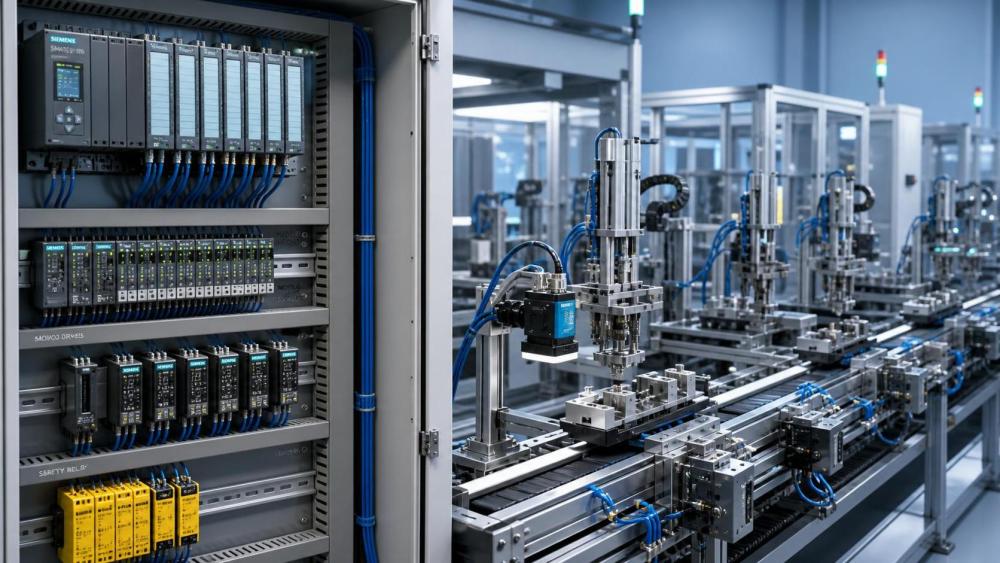
The choice between a central PLC with extensive local I/O and a distributed control architecture is not merely a cabinet-layout decision. It affects wiring cost, fault isolation, commissioning speed, expansion flexibility, network dependence, and the way maintenance teams troubleshoot a stopped line.
A centralized approach can work well for compact machines or short lines where devices are physically close to the main panel. It can simplify network design and make the control structure easy to understand. But as stations spread across a large assembly, packaging, material handling, or process line, long multi-core cables become harder to install, test, and modify. A single cabinet also concentrates heat, wiring density, and potential maintenance disruption.
Distributed I/O can reduce field wiring and place diagnostics closer to the equipment. It is often a strong fit for modular stations, longer conveyors, skids, or lines expected to expand. Yet distributed architecture does not remove complexity; it moves part of the complexity into network design, power distribution, environmental protection, and device management. A remote I/O rack in a poorly sealed enclosure, powered from an unstable local supply, can become less reliable than a centrally wired alternative.
For larger production lines, a common and often practical pattern is a line-level PLC or supervisory controller combined with station-level remote I/O, intelligent drives, and, where justified, local controllers for functionally distinct equipment. This arrangement can improve modularity, but only when the division of responsibility is explicit. Teams should define which controller owns pallet tracking, station enablement, fault escalation, safety-zone status, product recipes, and restart authorization.
A distributed system becomes difficult to maintain when control decisions are split across devices without a clear source of truth. For example, if a local station controller believes a pallet is available while the line controller has marked it as quarantined, the issue is not necessarily network speed. It is an application ownership problem. PLC sizing discussions should include this governance layer because adding more controllers can increase coordination risk as well as capacity.
Network Capacity Is More Than a Protocol Selection
Industrial Ethernet has made it easier to connect PLCs, drives, remote I/O, HMIs, vision equipment, and higher-level software. It has also encouraged some projects to place too much traffic on one network without separating critical control communication from less predictable data flows.
Protocol compatibility is necessary, but it does not answer the key questions. Evaluators need to know how many devices will be connected, how often each device exchanges data, which messages are cyclic, which are event-driven, and what happens when a device disconnects or restarts. A line may appear acceptable in a topology diagram while becoming vulnerable during firmware updates, camera data transfers, remote access sessions, or heavy HMI diagnostic activity.
Network segmentation is usually worth considering when a line includes several of the following: numerous variable-speed drives, motion devices, vision inspection, RFID or serialization systems, machine-to-machine coordination, remote maintenance access, and links to plant IT. Segmentation may use physical separation, managed switches, logical network design, or a combination of these approaches. The appropriate choice depends on the plant’s cybersecurity policy, maintenance capability, and the network features supported by the selected automation platform.
It is also important to verify how the PLC platform handles communication failures. A reliable design does not assume that every node will always be reachable. It defines timeouts, fallback states, fault messages, restart sequences, and whether a failed non-critical device should stop the line, bypass a station, or allow controlled operation in a degraded mode. These decisions frequently have greater availability impact than small differences in nominal network bandwidth.
Safety and Standard Control Must Be Sized Together
Safety PLCs, safety I/O, safety-rated drives, light curtains, interlocks, emergency stops, and safety communication networks should not be treated as an isolated package added after the production controls are selected. Safety behavior affects machine zoning, restart logic, operator access, maintenance procedures, and the availability of the entire line.
Where multiple stations share guards, transfer mechanisms, or robotic cells, safety zoning deserves early analysis. A broad safety zone may be easier to design initially, but every intervention can stop a larger portion of the line. Excessive segmentation, on the other hand, may increase validation effort, wiring, software complexity, and the risk of unclear restart conditions. The correct balance depends on the hazard assessment and production recovery requirements.
Technical teams should confirm the applicable safety standards and local regulatory requirements for the installation jurisdiction. Standards commonly referenced in machine safety work may include ISO 13849, IEC 62061, IEC 61508, IEC 60204-1, and relevant regional machinery regulations, but applicability must be confirmed for the specific machine, market, and project scope. Certification claims, performance level targets, and safety integrity targets should be reviewed against the complete design rather than assumed from the use of safety-rated components.
A frequent mistake is selecting safety hardware based only on the count of emergency-stop devices and guard switches. The final scope may expand when safe torque off, safe speed monitoring, muting, access gates, zone-reset stations, and safety feedback from third-party equipment are included. Spare safety I/O should be considered where line modifications are likely, but it should be planned within the validation strategy rather than added casually after the design is approved.
Plan Expansion, but Do Not Buy Unlimited Headroom
Future-proofing is valuable when it is tied to credible changes. It becomes wasteful when it is used as a vague reason to specify the largest available PLC, oversized cabinets, and unused communication capacity.
The better approach is to identify the most likely expansion paths. A manufacturer may expect to add two workstations within three years, introduce more product variants, connect a new vision station, or require additional production data for customer reporting. Each scenario affects a different part of the system. More stations may require physical I/O capacity and network ports. More variants may require memory, recipe handling, and software architecture. More inspection may require interface capacity and data buffering rather than more standard I/O.
Expansion planning should cover physical and engineering capacity. Leaving space in a panel is not sufficient if the selected power supply, network switch, PLC rack, software license, or safety design cannot support the additional equipment. Similarly, selecting a larger CPU is of limited value if the program is written as a tightly coupled sequence that cannot accommodate new stations without major changes.
For procurement teams, this means comparing lifecycle cost rather than only the initial controller price. The least expensive bill of materials can become the most expensive option if it requires a control-platform replacement during a line extension. At the same time, a premium architecture may be difficult to justify where the line is stable, compact, and unlikely to change. The decision should be anchored to the investment horizon and the realistic cost of downtime, retrofit work, and revalidation.
Assess Maintainability as a Capacity Requirement
PLC systems are maintained by people working under production pressure. A technically capable architecture can still produce long outages if technicians cannot identify the fault source, understand the station state, or restore operation safely after replacement of a device.
Maintainability begins with the selection of components and platforms that the site can support. This does not require standardizing every application on one supplier, but it does require an honest view of local skills, spare-parts availability, programming-tool access, and vendor support arrangements. A globally known automation brand may still present a risk if its specific controller series, service network, or certified repair path is not practical in the installation region.
Diagnostic design should be assessed during technical evaluation, not left to the commissioning phase. Useful diagnostics identify whether a stop originates from material absence, a sensor disagreement, a drive fault, a safety condition, an upstream block, a downstream starve condition, or a communications issue. They should also indicate what condition must be restored before a reset is accepted. A generic “station fault” message may be adequate for a small machine; it is rarely adequate for a high-output multi-station line.
Review how the proposed system handles online changes, software backup, version control, controller replacement, and remote support. Cybersecurity controls may restrict remote access, but the resulting service process must still be workable. The ability to retrieve the correct approved program, replace a failed CPU, restore parameters, and confirm device configuration can materially affect downtime exposure.
Questions That Expose Weak Sizing Assumptions
During supplier discussions, the most revealing questions are usually specific and operational. Technical evaluators should ask for answers that can be documented, tested, or demonstrated rather than broad assurances of “sufficient capacity.”
- What is the expected controller load at target throughput, and what communication traffic is included in that calculation?
- Which tasks require deterministic timing, and what response-time assumptions have been used?
- How are station handshakes designed when a controller, remote I/O node, drive, or vision device is temporarily unavailable?
- Which functions remain available when higher-level data systems are offline?
- How are safety zones defined, and what is the expected recovery sequence after a safety stop?
- What unused I/O, memory, network, power, and panel capacity is included, and what future scenario does each allowance support?
- Can the proposed platform be serviced locally, including hardware replacement, software licensing, and access to trained personnel?
- What factory and site acceptance tests will verify performance at production speed and under representative fault conditions?
Answers to these questions help distinguish a controller selection based on engineering evidence from one based on catalog familiarity. They also create a more useful record for procurement, project management, and future expansion decisions.
The Decision Is About Control Risk, Not Controller Size
Reliable PLC systems for multi-station production lines are sized by understanding where control delay, loss of visibility, or unclear ownership would disrupt production. I/O count remains an essential input, but it is only one part of the decision. Cycle-time requirements, communication behavior, distributed architecture, safety zoning, maintainability, and planned change all shape the real capacity requirement.
For technical evaluators, the strongest outcome is not simply a larger PLC. It is an architecture with enough measured margin, clear functional boundaries, diagnosable fault behavior, and a credible path for the changes the business is likely to make. That is the difference between a line that merely starts up and one that can continue operating predictably through years of product, process, and supply-chain change.
Industry Briefing
Get the top 5 industry headlines delivered to your inbox every morning.